GPT-6.2 Astra vs Claude Fable 5.2, Opus 5.5 and Gemini 4 Argon
GPT-6.2 Astra matches Claude Fable 5.2's high-effort score for about a quarter of the cost per task and leads Vals' science boards. We compare it with Fable 5.2, Opus 5.5, Gemini 4 Argon and GPT-6 Astra.
WidelAI Research
Evidence-led analysis for practical multi-model AI decisions
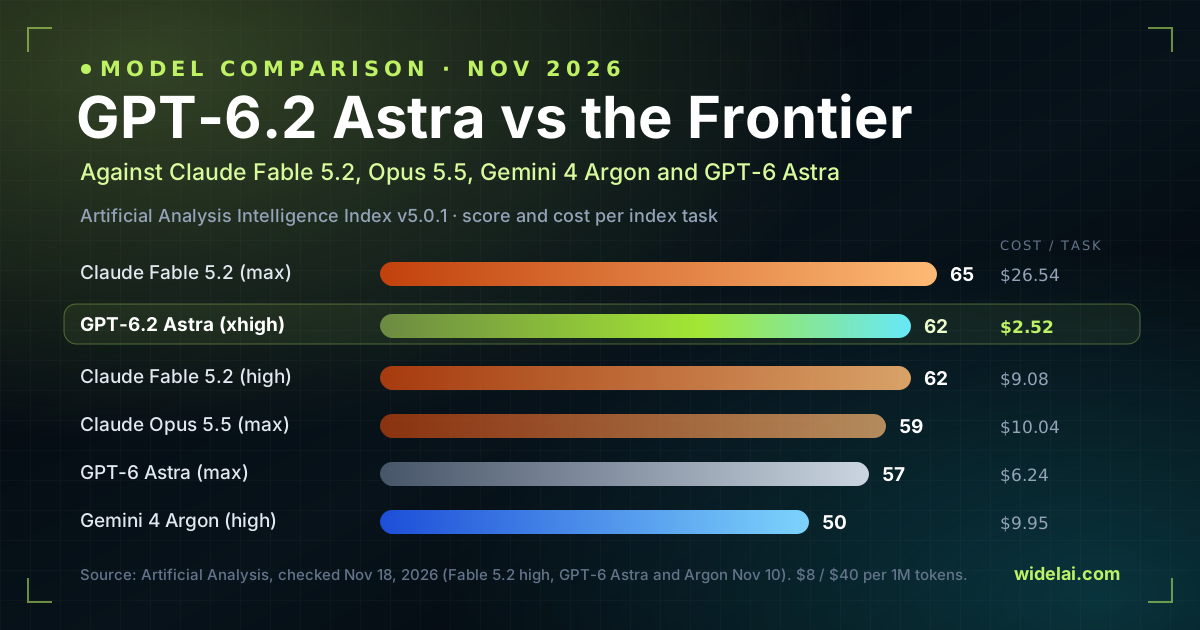
GPT-6.2 Astra is OpenAI's new frontier model for its hardest projects. It shipped on November 17, 2026 as gpt-6.2-astra, about eleven weeks after GPT-6 Astra, alongside a cheaper everyday sibling, GPT-6.2 Sol. Like Claude Fable 5.2 eight days earlier, it scores higher and costs less than the model it replaces: input is $8 per million tokens and output is $40, 20% below GPT-6 Astra, and cached input drops 60% to $0.40.
The short version: one day in, GPT-6.2 Astra scores 62 on the Artificial Analysis Intelligence Index, third of 92 models and three points behind Claude Fable 5.2 at max. The interesting number is the price of getting there. At xhigh effort Astra reaches the same 62 as Fable 5.2 at high for $2.52 per task against $9.08, and it is first on both of Vals AI's science boards. It is not the best model for everything: Fable 5.2 still leads both independent indices, Claude Opus 5.5 ties Fable on Terminal-Bench, and Astra sits in the middle of Vals' legal, finance and tax tables.
This guide compares GPT-6.2 Astra with the models you would weigh it against: Claude Fable 5.2, Claude Opus 5.5, Google's Gemini 4 Argon and its own predecessor GPT-6 Astra, with Gemini 4 Carbon and GPT-6.2 Sol where the independent numbers help. Every chart below is interactive: pick a benchmark, drag the sliders, or tap a dot. GPT-6.2 Astra is live on WidelAI today, in chat and in WidelCode, next to every model it is compared with.
Sources: OpenAI's GPT-6.2 Astra and Sol announcement and GPT-6.2 Astra model page; Artificial Analysis model pages, Intelligence Index v5.0.1; Vals AI model pages and the Vals Index; Anthropic's Fable 5.2 announcement and pricing; Google's Gemini 4 Argon model page. GPT-6.2 Astra figures were checked on November 18, 2026; figures for the other models come from our November 10 checks unless marked. Claims marked OpenAI-reported come from OpenAI's launch post.
Frontier score, a fraction of the frontier price
- AA Intelligence Index
- 62
- Third of 92 models. Fable 5.2 leads at 65
- Cost per AA task, xhigh
- $2.52
- Fable 5.2 scores the same 62 for $9.08
- Vals Science Index
- 68.44%
- First of 27, ahead of Fable 5.2 and GPT-6 Astra
- Input / output per 1M
- $8 / $40
- 20% below GPT-6 Astra; cached input $0.40
Sources: Artificial Analysis; Vals AI; OpenAI model page
The Short Answer
- Best value at the frontier: GPT-6.2 Astra. 62 on the Artificial Analysis index at xhigh for $2.52 a task, the same score Fable 5.2 reaches at high for $9.08 and three points above Opus 5.5 at max ($10.04).
- Strongest model overall: still Claude Fable 5.2. First on the Vals Index (71.31%) and the Artificial Analysis index (65 at max). Astra is seventh of 41 on Vals at 67.66%.
- Best for scientific computing: GPT-6.2 Astra. First of 47 on Vals' Terminal-Bench-Science (71.43%) and first of 27 on the Vals Science Index (68.44%), 15.7 points clear of Fable 5.2 on the former.
- Best for hard agentic coding: Fable 5.2 or Opus 5.5. They tie at 65.15% on Vals' Terminal-Bench 4.0; Astra is fifth at 63.13%.
- Not the pick for law, tax or finance agents. Astra is 22nd on the Vals Legal and Finance indices and 55th of 89 on Tax Agent Bench. Gemini 4 Argon, Opus 5.5 and Fable 5.2 lead those boards.
- If you use GPT-6 Astra today, switch. GPT-6.2 Astra is cheaper per token, cheaper per task ($4.00 against $6.24 at max) and higher on every independent score we checked.
What Changed from GPT-6 Astra
GPT-6.2 Astra keeps GPT-6 Astra's shape: a reasoning model with a 1,050,000-token context window, 128,000-token output limit, text and image input, and OpenAI's full Responses API tool set. The changes are in price, efficiency and scores.
| GPT-6 Astra | GPT-6.2 Astra | Change | |
|---|---|---|---|
| Input per 1M tokens | $10 | $8 | 20% lower |
| Cached input per 1M | $1.00 | $0.40 | 60% lower, now 0.05x input |
| Output per 1M tokens | $50 | $40 | 20% lower |
| Knowledge cutoff | Apr 30, 2026 | May 18, 2026 | About three weeks later |
| AA Index (max) | 57 | 62 | +5 points |
| Cost per AA task (max) | $6.24 | $4.00 | 36% lower |
| Vals Index v2.2 | 65.02% | 67.66% | +2.64 points |
| WidelAI credits per 1K (in / out) | 2.00 / 10.00 | 1.60 / 8.00 | 20% lower |
Prices from OpenAI's model pages. WidelAI bills 1 credit per $0.005 of provider API cost. Both models bill a whole request at 2x input and 1.5x output once the prompt passes 272K tokens.
Four things matter beyond the table:
- It spends fewer tokens. OpenAI says GPT-6.2 Astra beats GPT-6 Astra on its internal GDPval v2 by 6.2 points while using 22% fewer output tokens, and Harvey reports 34.5% fewer output tokens on its legal agent tasks. Token efficiency is why the cost per task falls further than the 20% price cut.
- The cache discount is now steep. Cached input bills at $0.40, a 95% discount on fresh input. OpenAI recommends keeping prompt prefixes unchanged and appending new instructions, so long agent sessions and repeated system prompts hit the cache.
- Effort can no longer be off. The API rejects a reasoning effort of none. The low setting is the floor, and on the Artificial Analysis index it scores 46 for $0.66 a task.
- Faster tiers cost more. Fast mode is twice the standard rate, and Ultrafast is three times through February 28, 2027 and six times after that. Batch is half price. WidelAI uses the standard tier.
The Models at a Glance
| Released | Context | Direct price (in / out per 1M) | AA Index (setting) | Cost per AA task | WidelAI credits per 1K (in / out) | |
|---|---|---|---|---|---|---|
| GPT-6.2 Astra | Nov 17, 2026 | 1.05M | $8 / $40 | 62 (max, xhigh) | $2.52 (xhigh) | 1.60 / 8.00 |
| Claude Fable 5.2 | Nov 9, 2026 | 1M | $8 / $40 | 65 (max), 62 (high) | $26.54, $9.08 | 1.60 / 8.00 |
| Claude Opus 5.5 | Sep 22, 2026 | 1M | $4 / $20 | 59 (max) | $10.04 | 0.80 / 4.00 |
| Gemini 4 Argon | Oct 13, 2026 | 1M | $2 / $10 to Nov 30, then $4 / $20 | 50 (high) | $9.95 | 0.40 / 2.00 until Nov 30 |
| GPT-6 Astra | Sep 3, 2026 | 1.05M | $10 / $50 | 57 (max) | $6.24 | 2.00 / 10.00 |
AA Index is the Artificial Analysis Intelligence Index v5.0.1 at the setting shown. Artificial Analysis prices Argon at Google's $4 / $20 standard rate. GPT-6.2 Astra accepts up to 922,000 input tokens of its 1.05M window.
Three things stand out before any benchmark:
- GPT-6.2 Astra and Fable 5.2 now cost exactly the same per token. Both are $8 / $40. The difference is in how many tokens each spends, and on the Artificial Analysis run Astra spends far fewer.
- Opus 5.5 is still half the price per token, but Astra at xhigh beats it on the index for a quarter of its cost per task.
- Argon's price advantage is a clock. At $2 / $10 it is a quarter of Astra's token price; from December 1 it is half.
The Frontier Map: Score Against Cost
Per-token prices hide the real cost of a reasoning model, which is tokens multiplied by how many the model spends on a task. Artificial Analysis runs every model at each effort setting and reports both the score and the cost per index task. Plot them together and GPT-6.2 Astra owns most of the efficient frontier.
Artificial Analysis Intelligence Index against cost per task
Each dot is one model at one effort setting. Up is smarter, left is cheaper. Tap a model to isolate it.
Hover, tap or tab through the dots. The glowing line is the efficient frontier: no model beats a point on it for both score and cost.
GPT-6.2 Astra, Sol, Fable 5.2 (max), Opus 5.5 and Carbon checked November 18, 2026; Fable 5.2 (high, medium), GPT-6 Astra and Argon from our November 10 check.
| Model and setting | AA Index v5.0.1 | Cost per AA task | Time per task |
|---|---|---|---|
| Claude Fable 5.2 (max) | 65 | $26.54 | 41.1 min |
| GPT-6.2 Astra (max) | 62 | $4.00 | 12.9 min |
| GPT-6.2 Astra (xhigh) | 62 | $2.52 | 6.8 min |
| Claude Fable 5.2 (high) | 62 | $9.08 | Not listed |
| GPT-6.2 Astra (high) | 60 | $2.07 | 5.3 min |
| Gemini 4 Carbon (high) | 60 | $7.76 | 34.5 min |
| Claude Opus 5.5 (max) | 59 | $10.04 | 24.6 min |
| GPT-6.2 Sol (max) | 57 | $1.01 | 8.0 min |
| GPT-6.2 Astra (medium) | 57 | $1.62 | 4.2 min |
| GPT-6 Astra (max) | 57 | $6.24 | Not listed |
| Gemini 4 Argon (high) | 50 | $9.95 | Not listed |
| GPT-6.2 Astra (low) | 46 | $0.66 | 1.6 min |
Artificial Analysis. The index combines nine evaluations: AA-Briefcase, AutomationBench-AA, Terminal-Bench 4.0, FrontierCode-AA 2.0, AA-Omniscience, GDP.pdf, HLE-Diamond, CritPt and Terminal-Bench-Science. Time per task is output tokens divided by end-to-end output speed.
Three readings from this table shape the rest of the guide:
- xhigh is GPT-6.2 Astra's sweet spot. It matches max on the index for 37% less per task and half the time. Max adds nothing on this index.
- Astra is also fast per task. At xhigh it finishes an average task in 6.8 minutes, against 24.6 for Opus 5.5 at max and 41.1 for Fable 5.2 at max. Its raw output speed is modest at 53 tokens per second; it gets there by spending fewer tokens.
- GPT-6.2 Sol is the budget surprise. It scores 57, level with GPT-6 Astra at max, for $1.01 a task. OpenAI says it comes within half a point of Astra on Cognition's FrontierCode 2.0 at about a fifth of the cost. Sol is not on WidelAI yet; GPT-6.2 Astra is.
What Independent Tests Say
Vendors pick the benchmarks in their launch posts. Vals AI ran GPT-6.2 Astra at max effort on launch day across its coding, science, finance, legal and tax boards. Pick a benchmark below to compare it with the four models it competes with, or open the scoreboard to see who leads most rows.
GPT-6.2 Astra against the frontier, row by row
Independent results from Artificial Analysis and Vals AI, plus one OpenAI-reported row. The crown marks the leader.
AA Index · Nine-evaluation composite, best settingArtificial Analysis
| Benchmark | GPT-6.2 Astra | Claude Fable 5.2 | Claude Opus 5.5 | Gemini 4 Argon | GPT-6 Astra |
|---|---|---|---|---|---|
| AA Index | 62 | 65 | 59 | 50 | 57 |
| Cost per AA task | $2.52 | $26.54 | $10.04 | $9.95 | $6.24 |
| Vals Index | 67.66% | 71.31% | 70.14% | 69.39% | 65.02% |
| Terminal-Bench-Science | 71.43% | 55.71% | 47.14% | 44.29% | 62.86% |
| Science Index | 68.44% | 63.74% | 58.65% | 55.36% | 65.09% |
| Terminal-Bench 4.0 | 63.13% | 65.15% | 65.15% | 57.58% | 59.6% |
| Vibe Code Bench | 89.9% | 93.77% | 90.29% | 91.91% | 89.59% |
| Finance Agent | 60.75% | 69.47% | 67.85% | 67.66% | 60.43% |
| Legal Index | 69.68% | 69.17% | 72.37% | 76.78% | 68.39% |
| AA-3D | 1,318 | 1,271 | Not reported | Not reported | Not reported |
Vals ran GPT-6.2 Astra, Opus 5.5 and GPT-6 Astra at max and Fable 5.2 and Argon at high. Other models' Vals figures checked November 10, 2026.
Sources: Vals AI GPT-6.2 Astra; Vals Index; Artificial Analysis; OpenAI
Vals AI
| Model | Vals Index v2.2 | Cost per test |
|---|---|---|
| Claude Fable 5.2 (high) | 71.31% | $17.94 |
| Claude Sonnet 5.5 | 70.85% | $16.18 |
| Gemini 4 Carbon (high) | 70.45% | $10.51 |
| Claude Opus 5.5 (max) | 70.14% | $24.77 |
| Gemini 4 Argon (high) | 69.39% | $13.37 |
| GPT-6.2 Astra (max) | 67.66% | $10.68 |
| GPT-6 Astra (max) | 65.02% | $21.28 |
Vals Index v2.2. GPT-6.2 Astra is seventh of 41; Gemini 4 Hydrogen (68.49%) also sits above it.
| Vals benchmark | GPT-6.2 Astra | Fable 5.2 | Opus 5.5 | Gemini 4 Argon | GPT-6.2 Astra rank |
|---|---|---|---|---|---|
| Terminal-Bench-Science | 71.43% | 55.71% | 47.14% | 44.29% | 1 of 47 |
| Vals Science Index | 68.44% | 63.74% | 58.65% | 55.36% | 1 of 27 |
| Terminal-Bench 4.0 | 63.13% | 65.15% | 65.15% | 57.58% | 5 of 68 |
| Vibe Code Bench v1.1 | 89.90% | 93.77% | 90.29% | 91.91% | 8 of 132 |
| Finance Agent v2.1 | 60.75% | 69.47% | 67.85% | 67.66% | 26 of 44 |
| Vals Legal Index | 69.68% | 69.17% | 72.37% | 76.78% | 22 of 42 |
| Tax Agent Bench | 21.84% | 32.09% | 44.54% | Not reported | 55 of 89 |
From each model's Vals page. Ranks count every model Vals has run on that benchmark.
- Science is now Astra's, clearly. In our Fable 5.2 comparison the science order was contested: Anthropic's own run put Fable 5.2 ahead of GPT-6 Astra on Terminal-Bench-Science, and Vals put Astra ahead. GPT-6.2 Astra widens the Vals gap to 15.7 points and leads the Science Index outright; on its biology component, BioMysteryBench, it is third at 80.74%. OpenAI's own run reports a 9-point gain over GPT-6 Astra at less than a third of the cost.
- Coding is close but not first. Fifth on Terminal-Bench 4.0, two points behind the Fable 5.2 and Opus 5.5 tie, and eighth on Vibe Code Bench v1.1. It is, however, first of ten on Vals' newer Vibe Code Bench 1-100 (55.16%).
- Professional boards are mid-table. 22nd on the Legal and Finance indices and 55th on Tax Agent Bench. That sits awkwardly with OpenAI's claims for legal work, covered next, and is the strongest reason to test before you route legal or tax work to it.
- It is the cheapest model in the top seven per Vals test. $10.68 against $17.94 for Fable 5.2 and $24.77 for Opus 5.5.
What OpenAI's Launch Post Claims
OpenAI's charts are mostly relative claims rather than tables, so we list them as OpenAI states them. Treat these as vendor-reported.
- Agents' Last Exam (long-horizon professional work): a new high, 5.2 points above GPT-6 Astra at less than a third of the cost, and 5.5 points ahead of Claude Fable 5.2 at 5% of the cost. OpenAI notes its Fable 5.2 result excludes nine tasks that used a fallback model.
- Harvey LAB-AA v1.1 (legal deliverables): a new state of the art, more than doubling Fable 5.2's pass rate at about one-sixth of the cost. Vals' own Harvey-based board, HLAB-Vals, has GPT-6.2 Astra 11th of 42 at 16.25%, so the independent picture is less dramatic.
- GDPval v2 (OpenAI internal knowledge work): leads the models OpenAI tested, up 6.2 points from GPT-6 Astra with 22% fewer output tokens.
- AA-AnalystAgent (spreadsheets and reports): a new high, 62.5% of questions answered correctly on all five independent attempts.
- AA-3D (interactive 3D experiences): first at 1,318 Elo, ahead of Fable 5.2 (1,271) and GPT-6.2 Sol (1,259) in blind human votes.
- Slides, spreadsheets and documents: OpenAI's headline qualitative claim is that Astra's deliverables follow templates and field conventions more closely. Early testers back it: ClickUp reports about 40% fewer tokens and 30% fewer review rounds on generated apps, dashboards and slides.
Price per Task: Run a Simulation
What you actually pay depends on your workload's shape: how much context you send, how much of it is cached, and how long the answers are. GPT-6.2 Astra and Fable 5.2 share a token price, so the gap on any one request comes from cache rates (Fable 5.2 reads cache at $0.20, Astra at $0.40) and OpenAI's long-context tier above 272K tokens. Drag the sliders to model your own workload; the per-task differences in the frontier map above come on top, from how many tokens each model spends.
What a month of your workload costs on each model
Provider list prices per request, multiplied by runs per month. WidelAI credits are shown at 1 credit per $0.005.
Per-request list prices only; output includes reasoning tokens. Real per-task cost also depends on how many tokens each model spends, where GPT-6.2 Astra is markedly more efficient on the Artificial Analysis run.
On WidelAI the same logic applies in credits. A chat turn with 20,000 tokens of context and a 2,000-token answer costs:
| Model | Credits per 1K (in / out) | Credits for the example turn |
|---|---|---|
| Gemini 4 Argon, until Nov 30 | 0.40 / 2.00 | 12 |
| Claude Opus 5.5 | 0.80 / 4.00 | 24 |
| GPT-6.2 Astra | 1.60 / 8.00 | 48 |
| Claude Fable 5.2 | 1.60 / 8.00 | 48 |
| GPT-6 Astra | 2.00 / 10.00 | 60 |
The 2,000 output tokens include reasoning, which every model here bills as output, so the real gap follows the frontier map: a model that thinks for fewer tokens costs less for the same answer. Cache reads bill at 0.08 credits per 1K on GPT-6.2 Astra, against 0.04 on Fable 5.2 and Opus 5.5 and 0.20 on GPT-6 Astra. Above 272K input tokens a whole Astra request bills at 3.20 / 12.00 credits per 1K. Every rate is on the pricing transparency page.
Where GPT-6.2 Astra Does Not Win
A model this efficient is easy to oversell. These are the places the evidence points elsewhere:
- Overall quality ceiling: Claude Fable 5.2 leads both independent indices, by three points on Artificial Analysis and 3.65 on Vals.
- Agentic coding: Fable 5.2 and Opus 5.5 tie for first on Terminal-Bench 4.0, two points ahead; Fable 5.2 also leads Vibe Code Bench v1.1 and, in Anthropic's table, FrontierCode 2.0 against GPT-6 Astra.
- Legal research: Gemini 4 Argon leads the Vals Legal Index at 76.78%, seven points ahead.
- Tax work: Opus 5.5 scores 44.54% on Tax Agent Bench, more than double Astra's 21.84%.
- Finance agents: Fable 5.2 leads Finance Agent v2.1 by almost nine points.
- Raw output speed: 53 tokens per second is slow for a 2026 frontier model. It finishes tasks quickly by thinking less, not by streaming faster.
- Cheapest good-enough model: GPT-6.2 Sol scores 57 for $1.01 a task, and Argon is a quarter of Astra's token price until November 30.
Which Model to Use for Each Task
Pick the kind of work you do and the router below shows where the evidence points, with the runner-up. The same routing is in the table after it.
Which model should take this task?
Routing based on the independent results in this guide. Every model named here is on WidelAI.
Routed to
GPT-6.2 Astra
First of 47 on Vals' Terminal-Bench-Science (71.43%) and first on the Vals Science Index. It leads Fable 5.2 by 15.7 points on the former.
Also consider: Claude Fable 5.2, which Anthropic's own run places ahead of GPT-6 Astra.
Run it on WidelAI| If you need... | Use | Why |
|---|---|---|
| Scientific computing and data science | GPT-6.2 Astra | First on Vals Terminal-Bench-Science (71.43%) and the Science Index |
| Frontier quality at the lowest cost per task | GPT-6.2 Astra at xhigh | 62 on the AA index for $2.52, against $9.08 for Fable 5.2 at the same score |
| Spreadsheets, slides and investment memos | GPT-6.2 Astra | New highs on AA-AnalystAgent and GDPval v2 (vendor-reported); test on your templates |
| Interactive web apps and 3D | GPT-6.2 Astra | First on AA-3D and on Vibe Code Bench 1-100 |
| The highest overall ceiling | Claude Fable 5.2 | First on both independent indices |
| Hard agentic coding | Claude Fable 5.2 or Opus 5.5 | Tied first on Terminal-Bench 4.0 at 65.15% |
| Legal research | Gemini 4 Argon | 76.78% Vals Legal Index; Astra is 22nd |
| Tax work | Claude Opus 5.5 | 44.54% Tax Agent Bench, double Astra |
| A daily driver at half the token price | Claude Opus 5.5 | 59 on the AA index at $4 / $20 |
| GPT-6 Astra workloads | GPT-6.2 Astra | Cheaper per token and per task, higher on every independent row |
A sensible setup after this launch: keep Opus 5.5 as the everyday default, send science, data and document work to GPT-6.2 Astra at xhigh, escalate the hardest coding to Fable 5.2 at high, and route legal research to Argon. If you run GPT-6 Astra today, move every workload to GPT-6.2 Astra.
Caveats Before You Switch
- The independent numbers are one day old. Artificial Analysis and Vals published on launch day. Expect movement as more runs land, as there was after Argon and Fable 5.2 shipped.
- Effort settings differ across evaluators. Vals ran Astra at max and Fable 5.2 at high; Artificial Analysis ran every setting. Compare like with like where you can.
- OpenAI's charts are OpenAI's. Its strongest claims, on Agents' Last Exam and Harvey LAB-AA, are vendor-run, and Vals' legal boards do not reproduce the legal lead.
- Tighter cyber safeguards. OpenAI says GPT-6.2 Astra meets its Critical threshold for cybersecurity and ships with stricter safeguards that also restrict some legitimate vulnerability research. Security teams should expect more refusals than on GPT-6 Astra.
- It can stay quiet about blockers. OpenAI's launch post notes the model was more likely to omit obstacles that blocked its work, such as a missing file, in two alignment tests. Ask agents to report what they could not do.
- Test on your own work. Five to ten tasks you have already solved will tell you more than any leaderboard.
Try GPT-6.2 Astra on WidelAI and WidelCode
GPT-6.2 Astra is live on WidelAI now, next to Claude Fable 5.2, Claude Opus 5.5, Gemini 4 Argon and GPT-6 Astra, on one plan and one credit balance.
In WidelAI chat
- Pick GPT-6.2 Astra from the OpenAI group in the chat model picker. It costs 1.60 input and 8.00 output credits per 1K tokens, 20% less than GPT-6 Astra, with cache reads at 0.08 credits per 1K.
- Set the effort. The reasoning effort control sets how long Astra thinks. Start at Extra (OpenAI's xhigh), which matched max on the Artificial Analysis index at 37% less cost, and drop to medium for routine work.
- Compare it in the same thread. Ask Astra first, then switch the picker to Fable 5.2, Opus 5.5 or Argon and send the same prompt. The history carries over, so you can read the answers side by side and see each one's credit cost.
- Give it a real deliverable. Astra's biggest gains are on work with a finished artifact: a forecast workbook from your numbers, an analysis of a dataset you upload, or a memo that follows your template.
In WidelCode
WidelCode, the WidelAI coding agent, lets you choose the model per task. The model ID everywhere is gpt-6.2-astra.
- Mac app: open the Code tab, choose a project folder and pick GPT-6.2 Astra in the OpenAI group. If you do not have the app yet, download WidelCode.
- CLI: install it once with
npm install -g widelcodeand sign in withwidelcode login. Start a session withwidelcode --model gpt-6.2-astra, or switch an existing one with/model gpt-6.2-astra. - VS Code: the
widelai.widelcodeextension, on the Visual Studio Marketplace and Open VSX, runs the same agent with the same models and credits. - Cloud agents: give Astra a data or science task that ends in a pull request, with a hard credit limit:
widelcode --model gpt-6.2-astra --budget 300 cloud run --repo your-org/your-repo --prompt "Profile the slowest analysis notebook, rewrite the hot path, and open a PR with before and after timings" --follow
New to WidelAI? Create your account and choose the Pro plan, which includes GPT-6.2 Astra, every other model in this guide and WidelCode. You can see every model and its rate on the models page and the pricing transparency page.
The Verdict
GPT-6.2 Astra is not the strongest model you can use today; Claude Fable 5.2 still is, on both independent indices. What Astra changes is the price of frontier quality. It reaches Fable 5.2's high-effort score on the Artificial Analysis index for about a quarter of the cost per task, beats Opus 5.5 at max for a quarter of its cost, and takes first place on both of Vals' science boards.
That makes it the new default for science, data and document-heavy work, and an easy upgrade from GPT-6 Astra on every axis. It is not the model for legal research, tax or finance agents, where Argon, Opus 5.5 and Fable 5.2 lead clearly, and the hardest coding still goes to Fable 5.2 or Opus 5.5. Route by task, run Astra at xhigh, and measure the credits.
Related Reading
- Claude Fable 5.2 vs Opus 5.5, GPT-6 Astra and Gemini 4 Argon
- Gemini 4 Hydrogen vs Claude Sonnet 5.5, GPT-6.1 Terra and Gemini 4 Argon
- Gemini 4 Argon vs Claude Opus 5.5, GPT-6 Astra and Fable 5.1
- GPT-6 Astra vs Claude Fable 5.1: Which Model Should You Use?
- The WidelCode CLI and VS Code Extension Are Now Available

Do your best AI work in one place
Bring your next question, draft, file, or idea to WidelAI. Choose the model that fits the moment, keep your work together, and stay in control of privacy and usage.
Leading models, one workspace
Use powerful AI models without juggling separate tabs, accounts, or workflows.
Switch without starting over
Change models as your work evolves while keeping the conversation and context together.
The right model for every task
Choose speed for everyday work or deeper reasoning for complex questions and decisions.
Clear credits and model rates
See your balance, understand each model’s rate, and track usage from one place.
Bring your files and images
Work with documents and images alongside your prompts in the same focused experience.
Your work stays yours
Your data is encrypted in transit and at rest, and your content is never used to train AI models.