AI Coding Agents Compared: Claude Code, Codex, Cursor, Kiro & WidelCode
Claude Code, Codex, Cursor, Kiro, Copilot, Antigravity, Devin Desktop and WidelCode compared on the latest pricing, models, features, and cost control.
WidelAI Research
Evidence-led analysis for practical multi-model AI decisions
AI coding agents are no longer autocomplete with a chat box. Every serious tool now plans work, edits many files, runs your tests, and loops until something passes. What separates them in late September 2026 is less about raw capability and more about three questions: which models you are allowed to use, how the bill is metered, and how much control you keep over what the agent does on your machine.
The past few weeks moved the market more than the previous six months. Anthropic shipped Claude Opus 5.5 on September 22 and made it the default Opus model in Claude Code. OpenAI launched GPT-6 Astra on September 3, then GPT-6 Sol and GPT-6 Luna on September 22, and all three now run in Codex. Google made Gemini 3.8 Flash generally available on September 2. SpaceXAI closed its acquisition of Cursor on August 14, and OpenAI responded by giving notice that its models will stop working in Cursor on November 12, 2026. Cognition released its SWE-2 coding model for Devin Desktop on September 10.
This guide compares eight tools on the facts we could verify against vendor pages as of September 27, 2026: Claude Code, OpenAI Codex, Cursor, Kiro, GitHub Copilot, Google Antigravity, Devin Desktop (formerly Windsurf), and WidelCode, the native macOS coding agent we build at WidelAI. We are obviously not neutral about the last one, so we have tried to be specific about where it leads, where it trails, and who should pick something else.
The charts and tools in this article are interactive. They use the same figures as the tables, with sources, so you can explore the numbers instead of taking our word for them. Start with the overview: filter the eight tools by family to see who makes each one, which model providers it can use, and what its cheapest paid plan costs.
Eight AI coding agents, side by side
Filter by family to see how each tool is built, who makes the models it can use, and what the cheapest paid plan costs.
8 tools shown
Claude Code
Anthropic
from $20/mo
Model-maker agent, CLI, IDE extensions, web
Best for: Terminal-first developers who are happy on Claude models
- Anthropic
Free: Not included on Claude's Free plan
OpenAI Codex
OpenAI
from $20/mo
Model-maker agent, Desktop app, CLI, IDE, cloud
Best for: ChatGPT subscribers who want parallel agents with worktrees
- OpenAI
Free: Included with ChatGPT Free and Go, limited
Cursor
Anysphere, now part of SpaceXAI
from $20/mo
Multi-model editor, Editor, cloud agents
Best for: Developers who want the most polished agentic editor
- SpaceXAI
- Cursor
- Anthropic
- OpenAI(until November 12, 2026)
Free: Hobby, limited agent requests
Kiro
AWS
from $20/mo
Multi-model editor, IDE, CLI, Web
Best for: Teams that want specs, hooks and shared conventions
- Anthropic
- OpenAI
- Open-weight
Free: 50 credits a month
GitHub Copilot
GitHub
from $10/mo
Multi-model editor, IDE extensions, CLI, GitHub
Best for: The lowest entry price and GitHub-centric work
- OpenAI
- Anthropic
Free: 2,000 inline suggestions a month, limited chat and agent
Google Antigravity
Google
from $19.99/mo
Model-maker agent, Desktop app, CLI, SDK
Best for: Google-ecosystem developers who want multi-agent orchestration
- Select third-party(at some tiers)
Free: Free individual tier with a weekly quota
Devin Desktop
Cognition
from $20/mo
Multi-model editor, Desktop, CLI, Devin Cloud
Best for: Handing whole tasks to a cloud agent and reviewing the PR
- OpenAI
- Anthropic
- SpaceXAI
- Open-source
- Cognition(SWE-2)
Free: Light quota
WidelCodeOurs
WidelAI
from $19/mo
Native multi-model agent, Native macOS app
Best for: Mac developers who want every major model and visible costs
- Anthropic
- OpenAI
- Moonshot AI
- Zhipu AI
Free: Free download, a plan is required to run it
Cheapest paid individual plan per month, checked September 27, 2026. We make WidelCode.
What Changed Recently in AI Coding Agents
If you last compared these tools in July, several of your assumptions are now out of date. The timeline below lists every change that matters, each linked to its source.
The releases and deals that reshaped AI coding agents
Every release, deal and deadline that changes which tool you should pick. Filter by what matters to you.
- Ownership
SpaceXAI closes its Cursor acquisition
The $60 billion all-stock deal for Cursor's parent, Anysphere, closes. Grok 4.6 ships inside Cursor the same week at $2/$6 per million tokens. Source for SpaceXAI closes its Cursor acquisition
- Ownership
OpenAI gives notice to Cursor
OpenAI will wind down its model contract with Cursor, with a proposed shutoff of November 12, 2026, and will not provide future models. Source for OpenAI gives notice to Cursor
- Models
Gemini 3.8 Flash is generally available
In the Gemini API, AI Studio and Antigravity at an introductory $0.75/$3.75 per million tokens through December 31, 2026. Source for Gemini 3.8 Flash is generally available
- Models
GPT-6 Astra launches
OpenAI's frontier model arrives at $10/$50 per million tokens and becomes available in Codex. Source for GPT-6 Astra launches
- Models
Cognition releases SWE-2 for Devin Desktop
Cognition says its new coding model comes close to Claude Fable 5.1 on FrontierCode at 64% lower cost. That is a vendor claim. Source for Cognition releases SWE-2 for Devin Desktop
- Features
Kiro gives GPT-5.6 a 1M-token context
GPT-5.6 Sol, Terra and Luna grow from 272K to 1M tokens in the Kiro IDE, CLI and Web, with doubled credit multipliers above 272K. Source for Kiro gives GPT-5.6 a 1M-token context
- Models
Claude Fable 5.1 previews in Kiro Enterprise
A preview rollout for Kiro Enterprise organizations, at a 6x credit multiplier. Source for Claude Fable 5.1 previews in Kiro Enterprise
- Models
Claude Opus 5.5 becomes Claude Code's default Opus
$4/$20 per million tokens, 20% below Opus 5, with cache reads down 60%. Pro and Team Standard plans now default to Opus. Source for Claude Opus 5.5 becomes Claude Code's default Opus
- Pricing
GPT-6 Sol and Luna reach Codex
Sol at $2/$10 and Luna at $0.10/$0.50 per million tokens, 50% below GPT-5.6 promotional pricing. Source for GPT-6 Sol and Luna reach Codex
- Features
Copilot adds assisted approvals
In public preview: low-risk tool calls in agent sessions are approved automatically, riskier ones still prompt you. Source for Copilot adds assisted approvals
- OwnershipUpcoming
Proposed end of OpenAI models in Cursor
The shutoff date OpenAI proposed. Plan a replacement if your Cursor workflow depends on GPT models. Source for Proposed end of OpenAI models in Cursor
Three changes stand out. Claude Opus 5.5 costs $4 per million input tokens and $20 per million output tokens, 20% below Opus 5, with cache reads cut 60% to $0.20 per million, and Anthropic says typical workloads cost about 40% less. It is now the default Opus model in Claude Code v2.1.280, Pro and Team Standard plans default to Opus instead of Sonnet, and five-hour usage limits went up on Pro, Max, Team, and seat-based Enterprise plans. GPT-6 Sol ($2/$10) and Luna ($0.10/$0.50) reached Codex at half the GPT-5.6 promotional price. And Cursor, now owned by SpaceXAI, faces the end of OpenAI models on November 12, 2026.
The pattern behind these events matters more than any single release. Model makers increasingly own the tools, and model access has become a competitive lever. The Cursor situation is the clearest example: a developer who built their workflow around GPT models inside Cursor now has a deadline that has nothing to do with code quality.
How We Grouped the Tools
AI coding agents now fall into three families, and knowing the family tells you most of what you are paying for.
- Model-maker agents. Claude Code (Anthropic), Codex (OpenAI), and Antigravity (Google). Each is tuned for its maker's models and usually bundled with that company's consumer subscription. You get the tightest model integration and the best per-dollar deal on that one provider's models.
- Multi-model editors and platforms. Cursor, Kiro, GitHub Copilot, and Devin Desktop. Full IDEs or IDE extensions that route to several providers, often alongside an in-house model (Composer, SWE-2) or an owner's model (Grok for Cursor).
- Multi-model native agents. WidelCode sits here. It is a native macOS app, not an editor, that runs the agent loop on your Mac and lets you pick a model from five providers for each prompt, billed at published per-model rates.
None of these families is strictly better. They make different trade-offs between integration depth, model freedom, and price predictability.
AI Coding Agent Pricing Compared
Individual plans, monthly prices in US dollars, as published on each vendor's pricing page on September 27, 2026.
| Tool | Free option | Entry paid plan | Mid tier | Top individual tier |
|---|---|---|---|---|
| Claude Code | Not on the Free plan | Pro $20 ($17/mo billed annually) | Max 5x $100 | Max 20x $200 |
| OpenAI Codex | Included with ChatGPT Free and Go, limited | Plus $20 | Pro 5x $100 | Pro 20x $200 |
| Cursor | Hobby, limited agent requests | Pro $20 | Pro+ $60 | Ultra $200 |
| Kiro | 50 credits/month | Pro $20 (1,000 credits) | Pro+ $40 (2,000), Pro Max $100 (5,000) | Power $200 (10,000) |
| GitHub Copilot | Free, 2,000 inline suggestions/month | Pro $10 (1,500 AI credits) | Pro+ $39 (7,000 AI credits) | Max $100 (20,000 AI credits) |
| Google Antigravity | Free individual tier, weekly quota | Google AI Pro $19.99 | Google AI Ultra $99.99 (5x) | Google AI Ultra $199.99 (20x) |
| Devin Desktop | Free, light quota | Pro $20 | None | Max $200 |
| WidelCode | Free download, no free usage tier | Starter $19 (2,000 credits) | Pro $49 (7,000 credits) | Enterprise, priced on request |
A few details change how these numbers read in practice:
- GitHub Copilot credits are dollars in disguise. One AI credit equals $0.01. Pro's $10 subscription includes $10 of base credits plus a $5 flex allotment, which is where the 1,500 figure comes from. Pro+ adds a $31 flex allotment to its $39 base, and Max adds $100 to its $100 base. GitHub notes that flex allotments may change over time. Inline suggestions stay unlimited on paid plans.
- Kiro bills fractionally. Credits are consumed in 0.01 increments, and each model carries a multiplier: Claude Opus 5 is 2.2x, Claude Sonnet 5 is 1.3x, and GPT-5.6 Sol is 4.4x for requests up to 272K tokens, doubling above that.
- Codex and ChatGPT Work share one allowance. OpenAI publishes estimated local messages per five-hour window for each plan and model, and a weekly limit may also apply. On Plus, the range for GPT-6 Sol (15-150) is roughly three times that for GPT-6 Astra (5-45), so the model you choose changes how far a plan goes. OpenAI also notes that higher reasoning effort uses more allowance and does not always produce a better result.
- Antigravity has no standalone subscription. Paid quota comes with Google AI plans and refreshes every five hours up to a weekly cap.
- WidelCode has no separate desktop price. The same WidelAI plan covers chat on the web and Android and the coding agent on the Mac. One credit corresponds to $0.005 of provider API cost, and every model's rate is published on the pricing transparency page.
Drag the budget to see what each tool gives you at a given price, then switch to the team view and change the team size. The order shifts as you go: Devin Desktop's $80 team fee makes it pricier than WidelAI Pro for teams of up to eight, and cheaper from nine developers up.
What your money buys in each tool
Each dot is a paid individual plan. Drag the budget to see the best plan each tool offers at that price.
Claude Code
Pro $20, $17/mo billed annually
Claude Code plans: Pro $20 ($17/mo billed annually); Max 5x $100; Max 20x $200. Best within $20: Pro $20 ($17/mo billed annually).
OpenAI Codex
Plus $20
OpenAI Codex plans: Plus $20; Pro 5x $100; Pro 20x $200. Free option: Included with ChatGPT Free and Go, limited. Best within $20: Plus $20.
Cursor
Pro $20
Cursor plans: Pro $20; Pro+ $60; Ultra $200. Free option: Hobby, limited agent requests. Best within $20: Pro $20.
Kiro
Pro $20, 1,000 credits
Kiro plans: Pro $20 (1,000 credits); Pro+ $40 (2,000 credits); Pro Max $100 (5,000 credits); Power $200 (10,000 credits). Free option: 50 credits a month. Best within $20: Pro $20 (1,000 credits).
GitHub Copilot
Pro $10, 1,500 AI credits
GitHub Copilot plans: Pro $10 (1,500 AI credits); Pro+ $39 (7,000 AI credits); Max $100 (20,000 AI credits). Free option: 2,000 inline suggestions a month, limited chat and agent. Best within $20: Pro $10 (1,500 AI credits).
Google Antigravity
Google AI Pro $19.99
Google Antigravity plans: Google AI Pro $19.99; Google AI Ultra 5x $99.99; Google AI Ultra 20x $199.99. Free option: Free individual tier with a weekly quota. Best within $20: Google AI Pro $19.99.
Devin Desktop
Pro $20
Devin Desktop plans: Pro $20; Max $200. Free option: Light quota. Best within $20: Pro $20.
WidelCode
Starter $19, 2,000 credits
WidelCode plans: Starter $19 (2,000 credits); Pro $49 (7,000 credits). Best within $20: Starter $19 (2,000 credits).
Monthly US list prices checked September 27, 2026, before tax and usage-based overage. Claude team seats and ChatGPT Business seats for Codex have plan-specific usage rules, so they are not charted.
Annual Cost for a Team of 10
Team pricing is where the differences compound. These figures use published per-seat list prices and ignore usage-based overage.
| Option | Per month (10 developers) | Per year |
|---|---|---|
| GitHub Copilot Business ($19/user) | $190 | $2,280 |
| WidelAI Starter x10 ($19 each) | $190 | $2,280 |
| Kiro Pro x10 ($20 each) | $200 | $2,400 |
| Google AI Pro x10 for Antigravity ($19.99 each) | $199.90 | $2,398.80 |
| Cursor Teams, Standard seats ($40/user) | $400 | $4,800 |
| GitHub Copilot Enterprise ($39/user) | $390 | $4,680 |
| Devin Desktop Teams ($80 plus $40 per developer seat) | $480 | $5,760 |
| WidelAI Pro x10 ($49 each) | $490 | $5,880 |
Claude Code team seats and ChatGPT Business seats for Codex are priced per seat with plan-specific usage rules, so check the current rate with each vendor before you budget. WidelAI does not yet sell a pooled team seat; teams buy individual plans or talk to us about Enterprise.
Feature Comparison: What Each Agent Actually Offers
| Capability | Claude Code | Codex | Cursor | Kiro | Copilot | Antigravity | Devin Desktop | WidelCode |
|---|---|---|---|---|---|---|---|---|
| Main surfaces | CLI, IDE extensions, web | Desktop app, CLI, IDE, cloud | Editor, cloud agents | IDE, CLI, Web | IDE extensions, CLI, GitHub | Desktop app, CLI, SDK | Desktop, CLI, Devin Cloud | Native macOS app |
| Model providers | Anthropic | OpenAI | SpaceXAI, Cursor, Anthropic, Google; OpenAI until Nov 12 | Anthropic, OpenAI, open-weight | Several major providers | Gemini first, select others | OpenAI, Anthropic, Google, SpaceXAI, open-source, SWE-2 | Anthropic, OpenAI, Google, Moonshot, Zhipu |
| MCP servers | Yes | Yes | Yes | Yes | Yes | Yes | Yes | No |
| Hooks, skills, rules | Yes | Skills, plugins, automations | Yes | Yes (hooks, steering, skills) | Custom agents and instructions | Yes | Yes | No, fixed system prompt |
| Parallel or background work | Subagents, cloud sessions | Worktrees, cloud tasks | Cloud agents | Kiro Web, parallel spec tasks | Cloud agent opens PRs | Parallel agents, scheduled tasks | Devin Cloud | Parallel local sessions only |
| Spending guardrail | Five-hour and weekly limits | Plan allowance | Included usage, then overage | Credits, opt-in overage | AI credit allowance, buy more | Five-hour refresh, weekly cap | Quotas, extra usage at API price | Per-run credit ceiling, live cost meter |
Two rows deserve emphasis. Model providers determine your exposure to events like the OpenAI and Cursor split. Spending guardrails determine whether a long agent run can surprise you at the end of the month.
If you already know what you cannot live without, filter by it. Pick one or more must-haves and only the tools that fully support every one stay lit.
Filter the tools by what you actually need
Select one or more must-haves. A tool stays lit only if it fully supports every one.
Pick what you need. Tools that do not have it fade out.
| Tool | Runs on Windows or Linux | Connects to MCP servers | Background or cloud agents | Models from three or more providers | Works inside VS Code or JetBrains |
|---|---|---|---|---|---|
| Claude Code | Yes | Yes | Yes: Cloud sessions | No: Anthropic only | Yes |
| OpenAI Codex | Yes | Yes | Yes: Cloud tasks | No: Built around OpenAI | Yes |
| Cursor | Yes | Yes | Yes: Cloud agents | Yes: OpenAI models end November 12, 2026 | No: Is its own editor |
| Kiro | Yes | Yes | Yes: Kiro Web and Crew | Yes | No: Is its own IDE |
| GitHub Copilot | Yes | Yes | Yes: Cloud agent opens PRs | Yes | Yes |
| Google Antigravity | Yes | Yes | Yes: Scheduled background tasks | Limited: Gemini first, some third-party models | No: Own desktop app |
| Devin Desktop | Yes | Yes | Yes: Devin Cloud | Yes | Yes: Editor plugins |
| WidelCode | No: macOS 14 or later only | No: Fixed set of eight built-in tools | No: Local sessions only, several in parallel | Yes: Five providers, chosen per prompt | No: Standalone Mac app |
Capabilities as documented by each vendor on September 27, 2026. "Limited" means partial support and does not count as a match.
How the Models Behind the Agents Compare
An agent is only as good as the model driving it, and every tool here now lets you choose between several. Two kinds of numbers are worth knowing, and they do not always agree: what the model makers publish, and what independent evaluators measure with their own harnesses.
How the models behind the agents score
Switch between the vendor's own table and an independent evaluator. The gap between the two is part of the lesson.
Multi-step work in a command line. Opus 5.5 at xhigh effort, GPT-6 Astra at high effort as reported by OpenAI. Higher is better.
- Claude Opus 5.566.4%
- GPT-6 Astra57.9%
- Claude Fable 5.155.8%
- Claude Opus 552.3%
- GPT-5.6 Sol37.3%
Vendor-reported results. In Anthropic's table, GPT-6 Astra and GPT-5.6 Sol figures are as reported by OpenAI, and Opus 5.5 ran with production safeguards that fall back to other models on some tasks.
What the numbers say, and what they do not:
- Anthropic's own table puts Claude Opus 5.5 first on most agentic coding rows. It reports 66.4% on Terminal-Bench 4.0, against 57.9% for GPT-6 Astra (as reported by OpenAI) and 55.8% for Claude Fable 5.1. The one row where Astra leads is AutomationBench, 41.4% to 40.0%, run by Zapier.
- Independent runs are closer. Artificial Analysis measured Opus 5.5 at 59.6% on Terminal-Bench 4.0, level with GPT-6 Astra at xhigh effort. Opus 5.5 still tops its Intelligence Index v4.3 at 58, ahead of Fable 5.1 and Astra at 53.
- Token use changes the bill as much as price per token. Artificial Analysis counted about 119K output tokens per Intelligence Index task for Opus 5.5 at max effort, against about 27K for GPT-6 Astra. Even so, Artificial Analysis found its cost per task level with Opus 5, because each token costs less.
- The cheaper GPT-6 tiers are about cost, not new peaks. In Artificial Analysis's run, GPT-6 Sol scored 57 on its Coding Agent Index in the Codex harness, 2 points above GPT-5.6 Sol, at about half the cost per task. GPT-6 Luna scored 41, 2 points below its predecessor, at about 60% lower cost.
- Gemini 3.8 Flash is priced for volume. Google reports 54.9% on HLE-Verified, a vendor-reported result, and says the model deliberately spends more tokens on hard tasks, especially at higher effort levels.
The practical takeaway: no single model wins every task at every price. That is an argument for tools that let you switch models without switching tools.
The Model-Maker Agents: Claude Code, Codex, and Antigravity
Claude Code
Claude Code remains the reference agent for developers who live in a terminal. You run it in your project, it reads and edits files, runs commands, and iterates, and it now also runs inside VS Code, on the web, and in other editors through extensions. Its extensibility is the deepest in this comparison: MCP servers, hooks, skills, plugins with marketplaces, and subagents for splitting large jobs.
The September release changed the economics. With v2.1.280 on September 22, Claude Opus 5.5 became the default Opus model, and Pro and Team Standard plans now default to Opus as well. Anthropic's own table puts Opus 5.5 at 66.4% on Terminal-Bench 4.0, ahead of GPT-6 Astra at 57.9% (as reported by OpenAI) and Claude Fable 5.1 at 55.8%. These are vendor-reported numbers run at maximum effort, and Anthropic itself says benchmark margins have become a less reliable guide at this level. A fast mode with up to 2.5x speed costs $8/$40 per million tokens.
Choose it if you want the strongest Anthropic integration and you are happy on Claude models for everything. Watch out for the single-provider lock: there is no GPT, Gemini, Kimi, or GLM in the picker, and a Pro plan that now defaults to Opus can reach its five-hour limit faster than it did on Sonnet. Check /model after updating.
OpenAI Codex
Codex spans a desktop app for macOS and Windows, an open-source CLI, IDE extensions, and cloud tasks, all sharing one ChatGPT allowance. The desktop app is built as a command center: agents run in separate threads per project, built-in worktrees let several agents work on the same repository without conflicts, and skills, plugins, and automations extend it beyond writing code.
GPT-6 Astra, Sol, and Luna are all available in Codex. Sol is OpenAI's recommendation for complex coding and agent workflows, and Luna for focused, high-volume tasks. At $2/$10 per million tokens, Sol is five times cheaper than Astra on both input and output, and the Plus usage ranges reflect that.
Choose it if you already pay for ChatGPT and want parallel agents with clean worktree isolation. Watch out for the OpenAI-only default and usage that varies by model: the same plan covers very different amounts of work depending on whether you pick Astra, Sol, or Luna.
Google Antigravity
Antigravity is Google's agent-first platform: a desktop app with a parallel-agent command center, a CLI that replaced Gemini CLI for individual accounts in June, and an SDK for hosting custom agents. Gemini 3.8 Flash is now available in it, with a 1M-token context window and low, medium, and high thinking levels.
The September releases were steady rather than dramatic. Version 2.17.0 on September 22 let custom agents declare their own hooks and gave rules a separate 20,000-token budget so a large rules file no longer crowds out skills and MCP tools. The CLI gained direct messaging to running subagents on September 23.
Choose it if you work in the Google ecosystem and want multi-agent orchestration with a built-in browser. Watch out for quota opacity: limits meter agent work rather than prompts, and each parallel agent draws from the same pool.
The Multi-Model Editors: Cursor, Kiro, Copilot, and Devin Desktop
Cursor
Cursor is still the most polished agentic editor, with cloud agents, Bugbot code review, MCP, skills, and hooks on Pro. Its in-house Composer 2.5 model lists at $0.50/$2.50 per million tokens, and Grok 4.6, released with SpaceXAI in August, starts at $2/$6.
The ownership change is the story to plan around. OpenAI has said it will stop providing its models to Cursor, with a proposed shutoff of November 12, 2026, and that it will not supply future models. If your Cursor workflow depends on GPT models, you have about six weeks to validate an alternative inside or outside the editor.
Choose it if you want the richest IDE experience and are comfortable with Grok, Composer, Claude, and Gemini as your model set. Watch out for overage: once included usage is spent, additional usage is billed at model rates.
Kiro
Kiro, from AWS, is built around spec-driven development: requirements, design, and task documents that the agent works through, plus event-driven hooks and steering files for project conventions. It now spans the IDE, a CLI, Kiro Web, and Kiro Crew for longer-running delegated work, with per-user usage metrics exportable to OpenTelemetry for administrators.
Its model list grew considerably this summer: Claude Sonnet 5 and Opus 5, the GPT-5.6 family with 1M context since September 14, open-weight options, and a Fable 5.1 preview for Enterprise organizations at a 6x credit multiplier.
Choose it if your team benefits from structure and repeatable conventions more than from raw speed. Watch out for multipliers on premium models, which shrink a credit allowance quickly.
GitHub Copilot
Copilot has the broadest editor coverage and the tightest GitHub integration: agent mode in VS Code, Visual Studio, JetBrains, Eclipse, and Xcode, a CLI, code review on pull requests, and a cloud agent that turns issues into PRs. Pro+ and Max can delegate tasks to third-party agents such as Claude and Codex in preview.
September added assisted approvals for agent sessions, the ability to edit an earlier message and have Copilot rewind both the conversation and file changes, and organization-managed skills and instructions in local and cloud sessions.
Choose it if you want the lowest entry price and your work already lives in GitHub. Watch out for heavy agent use on Pro: 1,500 credits is $15 of model usage, and frontier models burn through that quickly.
Devin Desktop (Formerly Windsurf)
Cognition retired the Windsurf brand on June 2 and relaunched the editor as Devin Desktop, with an agent command center as the default surface and Devin Cloud for delegating work to a remote agent that returns a pull request. It supports the Agent Client Protocol, so other compatible agents can run inside it.
SWE-2, released September 10, is Cognition's most capable model to date, and Cognition is offering free SWE-2 usage on self-serve plans for a limited period in October 2026. Team pricing changed shape: $80 per month for the team plan plus $40 per full developer seat.
Choose it if you want to hand whole tasks to a cloud agent and review the resulting PRs. Watch out for extra usage, which is billed at API pricing once quotas run out.
Why WidelCode Is the Better Choice for Multi-Model Mac Developers
WidelCode is the Code tab in WidelAI for Mac. It is a native Swift and SwiftUI app, not a VS Code fork and not a web view, and its agent runs on your machine: it reads and edits files in a project folder you choose and runs commands in your own login shell, so the Node, Python, Swift, and test runners it uses are the ones you have installed. You can download it here.
The quickest way to understand how it works, and where its safety controls sit, is to watch a run. The simulation below follows the same rules as the app: which tools ask for approval in each permission mode, when checkpoints are saved, how credits are billed per turn, and what a credit ceiling does.
Watch a WidelCode run, step by step
A small bug fix, played turn by turn. Change the permission mode to see which steps stop for you, and switch models or set a credit ceiling to see what the run costs.
Permission mode
Model
Run credit ceiling
- Press Play run, or step through it with Next turn. Each card is one model turn and the tools it called on your Mac.
Illustrative token counts. Credits use WidelAI's published rates, rounded up to a whole credit per request. Approval rules match the app: read-only tools never ask, edits ask only in Ask every time, and commands ask unless you choose Full auto.
Here is where we think it genuinely beats every other tool in this comparison, and why.
1. Five model providers in one agent, chosen per prompt
WidelCode can drive any tool-capable model in the WidelAI catalog: Claude Opus 5.5, Claude Fable 5.1, and Claude Sonnet 5 from Anthropic; GPT-6 Astra, GPT-6 Sol, and GPT-6 Luna from OpenAI; Gemini 3.8 Flash from Google; Kimi K3 from Moonshot AI; and GLM-5.3 and GLM-5.3-Flash from Zhipu AI. Pro includes the full catalog; the pricing page lists what each plan includes. The model is chosen per prompt, so a single session can use Luna for a mechanical rename, Sol for the implementation, and Opus 5.5 for the one tricky concurrency bug.
No other tool here puts all five providers, including the Kimi and GLM families, behind one agent. Claude Code is Anthropic-only, Codex is built around OpenAI, Antigravity is Gemini-first, and Cursor is about to lose OpenAI. When a provider changes its terms or ships a better model, you change a dropdown, not your toolchain.
2. You can see the price before you spend it
Most subscriptions in this comparison meter usage in units you cannot see until you hit a limit: five-hour windows, weekly caps, flex allotments that "may change over time," or overage billed afterwards. WidelCode takes the opposite approach:
- Every model's input and output rate is published, and the credit formula is public: one credit is $0.005 of provider API cost.
- Each run shows a live cost meter as it works.
- You can set a credit ceiling per run. The backend enforces it, so a runaway loop stops at your number, not at your plan limit.
- Runs pause after 50 steps and ask before continuing, so a model that is not converging cannot keep billing quietly.
- When credits run out, generation pauses. There is no overage charge.
3. Safety controls you can reason about
An agent that edits your real files deserves real controls, and WidelCode's are simple enough to explain in a paragraph:
- Three permission modes. Ask every time, auto-accept edits while confirming commands (the default), or full auto.
- Per-command approvals. "Always allow" is keyed to the command's executable and lasts only for the session, and commands such as
sudo,git push --force, andgit reset --hardcarry an explicit warning in the approval sheet. - Folder scoping. File tools resolve every path, including symlinks, and refuse anything outside the project folder.
- Checkpointed edits. Revert a single edit, every change to one file, or the whole run, and review net changes per file with partial hunk selection.
- Credential hygiene. Your session lives in the macOS Keychain as device-only, updates are verified against our Developer ID before they install, and the app is signed and notarized by Apple.
4. One account instead of a stack of subscriptions
Many developers pay for a coding tool and separately for ChatGPT, Claude, or Gemini to think through problems away from the editor. A WidelAI plan covers chat on the web and Android and the coding agent on the Mac, with the same account and conversations, starting at $19 per month. There are no API keys to paste.
5. Parallel sessions without a cloud dependency
You can run several coding sessions at once, including several in the same project, each with its own history, checkpoints, and draft. You can queue the next few instructions while a run is still working, and sessions keep running while you switch to chat.
Where WidelCode is not the right pick yet
A comparison that only lists our wins would not be worth reading. WidelCode is a young product, and these gaps are real today:
- macOS only. It requires macOS 14 Sonoma or later. There is no Windows or Linux build, no CLI, and no IDE extension.
- No extensibility layer. It has no MCP support, hooks, subagents, or rules files such as AGENTS.md. The agent has a fixed set of eight tools: read, list, glob, grep, write, edit, a visible task plan, and run command.
- No cloud or background agents. Everything runs locally, which is the point, but it means nothing works while your Mac is asleep.
- Shell commands are not sandboxed. File tools are scoped to your project, but a command you approve can do anything your user account can, and checkpoints revert file edits made through the tools, not the side effects of commands.
- Review happens after the edit in the default mode. Auto-accept writes changes to disk and lets you review and revert them. Switch to "Ask every time" if you want to approve each write first.
- Heavy single-vendor use can be cheaper elsewhere. If you run Claude Opus all day and nothing else, a Claude Max plan's subscription limits will likely give you more Opus work per dollar than published per-token rates.
If you need MCP integrations, team-wide hooks, or Windows support today, Claude Code, Kiro, or Cursor will serve you better. If you want model freedom, visible costs, and a native Mac agent that works on your real environment, WidelCode is built for you.
What an Agent Run Really Costs
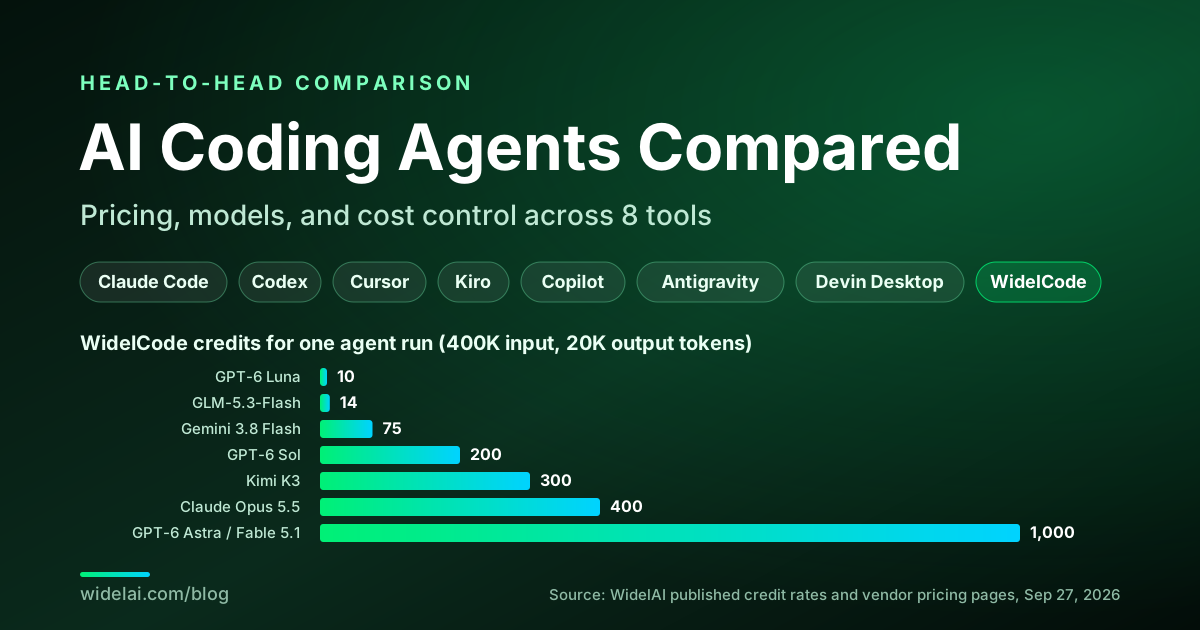
Subscription limits hide the unit economics, so here is the math for one representative agent run on WidelCode: roughly 25 turns that send 400,000 input tokens in total (the transcript is resent each turn) and generate 20,000 output tokens. The formula is:
credits = (input tokens / 1,000 x input rate) + (output tokens / 1,000 x output rate)
| Model | WidelAI rate per 1K (input / output) | Credits for this run | Provider cost equivalent |
|---|---|---|---|
| GPT-6 Luna | 0.02 / 0.10 | 8 + 2 = 10 | $0.05 |
| GLM-5.3-Flash | 0.03 / 0.10 | 12 + 2 = 14 | $0.07 |
| Gemini 3.8 Flash | 0.15 / 0.75 | 60 + 15 = 75 | $0.375 |
| GPT-6 Sol | 0.40 / 2.00 | 160 + 40 = 200 | $1.00 |
| Kimi K3 | 0.60 / 3.00 | 240 + 60 = 300 | $1.50 |
| Claude Opus 5.5 | 0.80 / 4.00 | 320 + 80 = 400 | $2.00 |
| GPT-6 Astra or Claude Fable 5.1 | 2.00 / 10.00 | 800 + 200 = 1,000 | $5.00 |
Credits round up to a whole number per request, so allow up to one extra credit per turn, or about 25 credits for this run. On a Pro plan's 7,000 monthly credits, that is about 17 runs of this size on Opus 5.5, 35 on GPT-6 Sol, or 700 on GPT-6 Luna. Starter's 2,000 credits cover 200 runs at 10 credits each, or 5 at 400.
Two conclusions follow. First, the model you pick matters far more than the tool: the same run spans a 100x range, from 10 to 1,000 credits. Second, this simple example applies full input rates to every token. Provider cache discounts are large (Opus 5.5 cache reads are $0.20 per million against $4 for fresh input), which is one reason subscription tools with aggressive caching can stretch further on long single-model sessions. OpenAI's GPT-6 Sol pricing shows the same pattern for direct API users: cached input costs 10% of the fresh rate, cache writes cost 1.25x, prompts above 272K input tokens are billed at 2x input and 1.5x output for the whole request, and Batch and Flex run at 50% of Standard rates. The practical lesson is to route: explore on Luna or GLM-5.3-Flash, implement on Sol or Gemini 3.8 Flash, and reserve Opus 5.5, Astra, or Fable 5.1 for the turns that need them. Our GPT-6 Sol vs GPT-6 Luna guide and Claude Opus 5.5 vs GPT-6 Sol comparison go deeper on those escalation decisions.
Try it with your own numbers. Set the size of a typical run and compare every model at once; tap a model to see what the run means against a WidelAI plan.
Price your own agent run
Set the size of a typical run. Every agent turn resends the transcript, so input tokens add up quickly. Tap a model to see what the run means against a plan.
Used only for rounding: each request rounds up to a whole credit.
Credits for this run, cheapest first
Claude Opus 5.5 costs about 400 credits for this run. The most expensive model costs 100x the cheapest for the same work.
Uses WidelAI's published credit rates, where one credit is $0.005 of provider API cost. Provider prompt-cache discounts are not applied, so direct-API costs for long single-model sessions can be lower than shown.
Which AI Coding Agent Should You Choose?
Answer four questions and the picker ranks the tools, showing exactly why each one scored where it did. We make one of these tools, so the scoring rules are printed under every pick. The table after it gives the same guidance at a glance.
Which AI coding agent fits you?
Answer four questions. The picks update as you go, with the exact reasons each tool scored where it did.
1What do you code on?
2What matters most?
3Anything you cannot live without?
4Monthly budget per person
Your top picks
#1
Devin Desktop
- Models from 6 sources
- Pro at $20 fits your $20 budget
#2
WidelCode
- Models from 5 sources
- Pick the model per prompt inside one session
- Starter at $19 fits your $20 budget
#3
Cursor
- Models from 4 sources
- Pro at $20 fits your $20 budget
We make WidelCode, so the scoring is shown in full rather than hidden. Hard requirements (platform, must-haves, budget) remove a tool; your top priority ranks what is left, and ties go to the cheaper tool.
| If you are... | Pick | Why |
|---|---|---|
| Solo developer on a tight budget | GitHub Copilot Pro ($10) | Lowest entry price, unlimited inline suggestions |
| Terminal-first, happy on Claude models | Claude Code Pro or Max | Deepest Anthropic integration and extensibility |
| Already paying for ChatGPT | Codex (Plus and up) | GPT-6 models, parallel agents, worktree isolation |
| Wants the most polished agentic editor | Cursor Pro | Cloud agents, Bugbot, Composer and Grok, if you can live without OpenAI after November 12 |
| Team that values structure and conventions | Kiro Pro or Pro+ | Specs, hooks, steering, and admin usage metrics |
| Deep in Google's ecosystem | Antigravity (Google AI Pro) | Gemini 3.8 Flash, multi-agent orchestration, browser |
| Wants to delegate whole tasks and review PRs | Devin Desktop Pro | Devin Cloud plus SWE-2 |
| Mac developer who wants every major model and visible costs | WidelCode (Starter or Pro) | Five providers per prompt, per-run credit ceilings, local agent, chat on web and Android included |
Many developers will end up with two tools. A common pairing is an editor-based agent for daily work plus a second agent on a different model family for second opinions. WidelCode fits that role well, because switching models mid-session is how you find the assumption one model made silently.
How to Cut Your AI Coding Costs
- Track two weeks of real usage before upgrading. Most people guess high or low by a factor of two.
- Route by task, not by habit. Mechanical edits do not need a frontier model. In WidelCode, set the model per prompt; in Kiro and Copilot, watch multipliers and per-model credit rates.
- Keep instruction files lean. Rules, CLAUDE.md, steering, and similar files are resent constantly. Antigravity's new 20,000-token rules budget exists because large rules files crowd out everything else.
- Clear context between tasks. A transcript that is resent every turn is the biggest hidden cost in any agent.
- Set hard ceilings where the tool allows them. A per-run credit budget in WidelCode or an overage cap in Kiro turns a surprise into a pause.
- Pay annually only for the tool you are sure about. Claude Pro drops from $20 to $17 per month on annual billing, but this market has changed ownership, models, and pricing within a single quarter.
- Plan for model access, not just price. If a single provider leaving your tool would stop your team, that is a risk worth pricing in.
Frequently Asked Questions
What is the cheapest AI coding agent?
GitHub Copilot Pro at $10 per month has the lowest paid entry price and includes 1,500 AI credits, equal to $15 of model usage, with unlimited inline suggestions. For a local agent with every major model, WidelAI Starter costs $19 per month with 2,000 credits, and economical models make those credits go a long way.
Will Cursor lose OpenAI models?
OpenAI announced in late August 2026 that it will wind down its contract providing models to Cursor after SpaceX's acquisition, with a proposed shutoff date of November 12, 2026, and that it will not provide future models to Cursor.
Which AI coding agent supports the most model providers?
Several tools are multi-model, including Cursor, Copilot, Kiro, and Devin Desktop. WidelCode is the one in this comparison that puts Anthropic, OpenAI, Google, Moonshot AI, and Zhipu AI models behind a single agent and lets you switch per prompt.
Is Claude Opus 5.5 the best model for coding?
On Anthropic's published table it leads Terminal-Bench 4.0 at 66.4%, and it costs $4/$20 per million tokens. Those are vendor-reported results, and the right model still depends on your task and budget, which is why routing between models usually beats picking one.
Does WidelCode support MCP or run on Windows?
Not today. WidelCode is macOS-only (macOS 14 or later) and has a fixed toolset without MCP, hooks, or subagents. It focuses on a local agent with model choice, visible costs, and reversible edits.
The Bottom Line
The best AI coding agent right now depends on which constraint you feel most. If you want the deepest single-vendor integration, the model makers' own agents are excellent: Claude Code for Anthropic, Codex for OpenAI, Antigravity for Google. If you want a full editor with many models, Cursor, Kiro, Copilot, and Devin Desktop each have a clear niche, though Cursor users relying on GPT models should plan for November 12.
WidelCode is for developers who refuse to bet their workflow on one model maker. It gives you five providers in one native Mac agent, prices every token in public, and puts a ceiling on every run. It is not the most extensible tool here yet, and we have said exactly where it falls short. But in a quarter when an acquisition could cut a provider out of a popular editor, model freedom and cost visibility are no longer nice-to-haves.
Browse every model on the models page, compare plans on the pricing page, or read the WidelAI for Mac launch post for more on how the agent works. For the models themselves, see what joined WidelAI in September 2026, the Gemini 3.8 Flash guide, and GPT-6 Astra vs Claude Fable 5.1.
Sources
Pricing and feature details were checked against these pages on September 27, 2026. Content was rephrased for licensing compliance.
- Anthropic: Introducing Claude Opus 5.5
- Anthropic: Claude Platform release notes
- OpenAI: Codex pricing, Managing usage in Work and Codex, GPT-6 Sol model pricing, GPT-6 Sol and Luna announcement, and ChatGPT release notes
- OpenAI: Introducing the Codex app
- OpenAI: Our decision on Cursor following its acquisition by SpaceX
- Cursor: Pricing, Models and pricing, and Introducing Grok 4.6
- Kiro: Pricing, Enterprise billing, and Models changelog
- GitHub: Copilot plans and pricing, Copilot licenses, and Copilot weekly releases, September 21
- Artificial Analysis: Claude Opus 5.5 takes the top spot, GPT-6 Sol and Luna push the cost efficiency frontier, and Intelligence Index v4.3
- Google: Antigravity, Antigravity release notes, via the gradually.ai changelog mirror, Gemini 3.8 Flash announcement and Google AI subscription updates from I/O 2026
- Cognition: Devin pricing and Windsurf is now Devin Desktop
- WidelAI: pricing transparency and WidelCode download

Do your best AI work in one place
Bring your next question, draft, file, or idea to WidelAI. Choose the model that fits the moment, keep your work together, and stay in control of privacy and usage.
Leading models, one workspace
Use powerful AI models without juggling separate tabs, accounts, or workflows.
Switch without starting over
Change models as your work evolves while keeping the conversation and context together.
The right model for every task
Choose speed for everyday work or deeper reasoning for complex questions and decisions.
Clear credits and model rates
See your balance, understand each model’s rate, and track usage from one place.
Bring your files and images
Work with documents and images alongside your prompts in the same focused experience.
Your work stays yours
Your data is encrypted in transit and at rest, and your content is never used to train AI models.